The cpufreq-stats code can no longer be built as a module, so it now
appears with square brackets in menuconfig.

Signed-off-by: Jean Delvare <jdelvare@suse.de>
Fixes: 1aefc75b24 (cpufreq: stats: Make the stats code non-modular)
Acked-by: Viresh Kumar <viresh.kumar@linaro.org>
Signed-off-by: Rafael J. Wysocki <rafael.j.wysocki@intel.com>
Since struct cpudata is defined in a header file, add prefix cppc_ to
make it not a generic name. Otherwise it causes compile issue in locally
define structure with the same name.

Signed-off-by: Srinivas Pandruvada <srinivas.pandruvada@linux.intel.com>
Signed-off-by: Rafael J. Wysocki <rafael.j.wysocki@intel.com>
The CPPC registers can also be accessed via functional fixed hardware
addresse(FFH) in X86. Add support by modifying cpc_read and cpc_write to
be able to read/write MSRs on x86 platform on per cpu basis.
Also with this change, acpi_cppc_processor_probe doesn't bail out if
address space id is not equal to PCC or memory address space and FFH
is supported on the system.

Signed-off-by: Srinivas Pandruvada <srinivas.pandruvada@linux.intel.com>
Signed-off-by: Rafael J. Wysocki <rafael.j.wysocki@intel.com>
It is still possible to continue even CPPC data is invalid or missing.

Suggested-by: Alexey Klimov <alexey.klimov@arm.com>
Signed-off-by: Srinivas Pandruvada <srinivas.pandruvada@linux.intel.com>
Signed-off-by: Rafael J. Wysocki <rafael.j.wysocki@intel.com>
Some newer x86 platforms have support for both _CPC and _PSS object. So
kernel config can have both ACPI_CPU_FREQ_PSS and ACPI_CPPC_LIB. So remove
restriction for ACPI_CPPC_LIB to build only when ACPI_CPU_FREQ_PSS is not
defined.
Also for legacy systems with only _PSS, we shouldn't bail out if
acpi_cppc_processor_probe() fails, if ACPI_CPU_FREQ_PSS is also defined.

Signed-off-by: Srinivas Pandruvada <srinivas.pandruvada@linux.intel.com>
Signed-off-by: Rafael J. Wysocki <rafael.j.wysocki@intel.com>
Depending on a number of factors including:
- Which exact Rockchip SoC we're working with
- How deep we suspend
- Which i2c port we're on

We might lose the state of the i2c registers at suspend time.
Specifically we've found that on rk3399 the i2c ports that are not in
the PMU power domain lose their state with the current suspend depth
configured by ARM Tursted Firmware.

Note that there are very few actual i2c registers that aren't configured
per transfer anyway so all we actually need to re-configure are the
clock config registers.  We'll just add a call to rk3x_i2c_adapt_div()
at resume time and be done with it.

NOTE: On rk3399 on ports whose power was lost, I put printouts in at
resume time.  I saw things like:
  before: con=0x00010300, div=0x00060006
  after:  con=0x00010200, div=0x00180025

Signed-off-by: Douglas Anderson <dianders@chromium.org>
Reviewed-by: David Wu <david.wu@rock-chips.com>
Tested-by: David Wu <david.wu@rock-chips.com>
[wsa: removed duplicate const]
Signed-off-by: Wolfram Sang <wsa@the-dreams.de>
Currently, the adapter is set to the master mode at the first use.
Since then, it is kept in the slave mode, so unexpected glitch
signals on the I2C lines may cause the adapter into insane state.
Setting it to the master mode along with initialization solves the
problem.

Signed-off-by: Masahiro Yamada <yamada.masahiro@socionext.com>
Reported-by: Akio Noda <noda.akio@socionext.com>
Signed-off-by: Wolfram Sang <wsa@the-dreams.de>
If clk_prepare_enable() fails, clk_disable_unprepare() is called in
the failure path, where the enable_count is still zero, so it hits
WARN_ON(core->enable_count == 0) in the clk_core_disable().

To fix this, make the clock setting more linear in the probe function
so that it can exploit "goto err" in case of error.

Signed-off-by: Masahiro Yamada <yamada.masahiro@socionext.com>
Signed-off-by: Wolfram Sang <wsa@the-dreams.de>
If clk_prepare_enable() fails, clk_disable_unprepare() is called in
the failure path, where the enable_count is still zero, so it hits
WARN_ON(core->enable_count == 0) in the clk_core_disable().

To fix this, make the clock setting more linear in the probe function
so that it can exploit "goto err" in case of error.

Signed-off-by: Masahiro Yamada <yamada.masahiro@socionext.com>
Signed-off-by: Wolfram Sang <wsa@the-dreams.de>
Fix the following warnings reported by coccinelle for the Tegra I2C
driver.

drivers/i2c/busses/i2c-tegra.c:513:2-23: WARNING: Assignment of bool to 0/1
drivers/i2c/busses/i2c-tegra.c:539:3-24: WARNING: Assignment of bool to 0/1

Reported-by: Wolfram Sang <wsa@the-dreams.de>
Signed-off-by: Jon Hunter <jonathanh@nvidia.com>
Signed-off-by: Wolfram Sang <wsa@the-dreams.de>
To summarize the issue observed in error cases:

SW Flow: For i2c message transfer, packet header and data payload is
posted and then required error/packet completion interrupts are enabled
later.

HW flow: HW process the packet just after packet header is posted, if
ARB lost/NACK error occurs (SW will not handle immediately when error
happens as error interrupts are not enabled at this point). HW assumes
error is acknowledged and clears current data in FIFO, But SW here posts
the remaining data payload which still stays in FIFO as stale data
(data without packet header).

Now once the interrupts are enabled, SW handles ARB lost/NACK error by
clearing the ARB lost/NACK interrupt. Now HW assumes that SW attended
the error and will parse/process stale data (data without packet header)
present in FIFO which causes invalid NACK errors.

Fix: Enable the error interrupts before posting the packet into FIFO
which make sure HW to not clear the fifo. Also disable the packet mode
before acknowledging errors (ARB lost/NACK error) to not process any
stale data. As error interrupts are enabled before posting the packet
header use spinlock to avoid preempting.

Signed-off-by: Shardar Shariff Md <smohammed@nvidia.com>
Signed-off-by: Wolfram Sang <wsa@the-dreams.de>
Use readl_poll_timeout_atomic() function as *wait_for_config_load()
function can be called from interrupt context.

Signed-off-by: Shardar Shariff Md <smohammed@nvidia.com>
Signed-off-by: Wolfram Sang <wsa@the-dreams.de>
Define separate function for configuration load register handling
to make it use by different functions later.

Signed-off-by: Shardar Shariff Md <smohammed@nvidia.com>
Signed-off-by: Wolfram Sang <wsa@the-dreams.de>
During i2c controller initialization, when fifo flush fails return error
instead of returning the error during exit.

Signed-off-by: Shardar Shariff Md <smohammed@nvidia.com>
Signed-off-by: Wolfram Sang <wsa@the-dreams.de>
After CONFIG_LOAD register is programmed instead of explicitly waiting
for timeout, use readl_poll_timeout() to check for register value to get
updated or wait till timeout.

Signed-off-by: Shardar Shariff Md <smohammed@nvidia.com>
Signed-off-by: Wolfram Sang <wsa@the-dreams.de>
"i2c-sh_mobile" is used on sh7343, sh7366, sh7722, sh7723, and sh7724
only. As all of the above select ARCH_SHMOBILE, restrict its driver
dependencies from SUPERH to ARCH_SHMOBILE.

Signed-off-by: Geert Uytterhoeven <geert+renesas@glider.be>
Reviewed-by: Simon Horman <horms+renesas@verge.net.au>
Signed-off-by: Wolfram Sang <wsa@the-dreams.de>
Under a strict subject/object security policy delivering a
signal or delivering network IPC could be considered either
a write or an append operation. The original choice to make
both write operations leads to an issue where IPC delivery
is desired under policy, but delivery of signals is not.
This patch provides the option of making signal delivery
an append operation, allowing Smack rules that deny signal
delivery while allowing IPC. This was requested for Tizen.

Signed-off-by: Casey Schaufler <casey@schaufler-ca.com>
There are several ways to set the SDA hold time for i2c controller,
including: Device Tree, built-in device properties and ACPI. However,
if the SDA hold time is not specified by above method, we should
read the value, where it is preset by firmware, and save it to
sda_hold_time. This is needed because when i2c controller enters
runtime suspend, the DW_IC_SDA_HOLD value will be reset to chipset
default value. And during runtime resume, i2c_dw_init will be called
to reconfigure i2c controller. If sda_hold_time is zero, the chipset
default hold time will be used, that will be too short for some
platforms. Therefore, to have a better tolerance, the DW_IC_SDA_HOLD
value should be kept by sda_hold_time.

Signed-off-by: Zhuo-hao Lee <zhuo-hao.lee@intel.com>
Reviewed-by: Andy Shevchenko <andriy.shevchenko@linux.intel.com>
Acked-by: Jarkko Nikula <jarkko.nikula@linux.intel.com>
Signed-off-by: Wolfram Sang <wsa@the-dreams.de>
Steffen Klassert says:

====================
ipsec 2016-09-08

1) Fix a crash when xfrm_dump_sa returns an error.
   From Vegard Nossum.

2) Remove some incorrect WARN() on normal error handling.
   From Vegard Nossum.

3) Ignore socket policies when rebuilding hash tables,
   socket policies are not inserted into the hash tables.
   From Tobias Brunner.

4) Initialize and check tunnel pointers properly before
   we use it. From Alexey Kodanev.

5) Fix l3mdev oif setting on xfrm dst lookups.
   From David Ahern.
====================

Signed-off-by: David S. Miller <davem@davemloft.net>
Steffen Klassert says:

====================
ipsec-next 2016-09-08

1) Constify the xfrm_replay structures. From Julia Lawall

2) Protect xfrm state hash tables with rcu, lookups
   can be done now without acquiring xfrm_state_lock.
   From Florian Westphal.

3) Protect xfrm policy hash tables with rcu, lookups
   can be done now without acquiring xfrm_policy_lock.
   From Florian Westphal.

4) We don't need to have a garbage collector list per
   namespace anymore, so use a global one instead.
   From Florian Westphal.
====================

Signed-off-by: David S. Miller <davem@davemloft.net>
Instead of rolling our own timer, just utilize the blk mq req timeout and do the
disconnect if any of our commands timeout.

Signed-off-by: Josef Bacik <jbacik@fb.com>
Signed-off-by: Jens Axboe <axboe@fb.com>
In preparation for some future changes, change a few of the state bools over to
normal bits to set/clear properly.

Signed-off-by: Josef Bacik <jbacik@fb.com>
Signed-off-by: Jens Axboe <axboe@fb.com>
We hit a warning when shutting down the nbd connection because we have irq's
disabled.  We don't really need to do the shutdown under the lock, just clear
the nbd->sock.  So do the shutdown outside of the irq.  This gets rid of the
warning.

Signed-off-by: Josef Bacik <jbacik@fb.com>
Signed-off-by: Jens Axboe <axboe@fb.com>
This moves NBD over to using blkmq, which allows us to get rid of the NBD
wide queue lock and the async submit kthread.  We will start with 1 hw
queue for now, but I plan to add multiple tcp connection support in the
future and we'll fix how we set the hwqueue's.

Signed-off-by: Josef Bacik <jbacik@fb.com>
Signed-off-by: Jens Axboe <axboe@fb.com>
The usual bunch of fixes to the our clock drivers, mostly targetted to the
 brand new sunxi-ng drivers.
 -----BEGIN PGP SIGNATURE-----
 Version: GnuPG v1

 iQIcBAABAgAGBQJX0GrSAAoJEBx+YmzsjxAg6skP/2Q/7rpL92sKten40JB3Lbsd
 H34VIytVAur3TjBHdQh9JMcIAAenEfyCf2rF0bolstesJsuWWKF9PcJl+yYb5CWK
 X9uy5tGQiR2//kmiXVXiSYfQa661SVF0eOEIPzjCaXNTVzfrFNN92RINoJkDmg7Q
 gNphHxzjHkjxVLaDUYyTWje8h9qYlaEu0Blt1TA1+q4NqVvLkWIrVF4e68unKkqb
 6oj7Acvj0B0EqGxXEh5xI9StGFWDMMKAZfTbqPpt+2mFlH5yP4CPVt9/3NlHUaoC
 3k9Z1wER+dgkjaDj2Z0s6UBMchm+NUJ6gWRYrAUOUsOhqMk523kjVxqG/bm8ZYGu
 u0TTD0kehTGFAMh8gE/IbLx649kbGsg0Fn9XGtajfs1WLnOs3jsIQcrEruPa8z+u
 86Zc6Ruikb/Llecr1aUbLpa4s7yZASmLWOH516My8oXIMe8k+JoOJvnBq0IM7+LB
 VeD3cV5KD5d4HBCGdnXtMN4pN9xcw4uIKNXXOgM5MSR/E3lxq9HhxNyYUK9I9/1x
 FKLGdJ1Z6tl+5osW0QjkhKCf7R4w6Rwib9f0MDR6NrsI4qMJFx5BhABKOfuHwXWq
 CtxxM2Ktz0WLYaA9faxG7G8mAwYDqaR8MseQ8bqOeE8cXleVoWupGAUrvwQmiqaw
 o4nfXYUwDJ6J42qfhNRj
 =axNZ
 -----END PGP SIGNATURE-----

Merge tag 'sunxi-clk-fixes-for-4.8' of https://git.kernel.org/pub/scm/linux/kernel/git/mripard/linux into clk-fixes

Clock Fixes for the Allwinner SoCs, 4.8 Edition

The usual bunch of fixes to the our clock drivers, mostly targetted to the
brand new sunxi-ng drivers.

* tag 'sunxi-clk-fixes-for-4.8' of https://git.kernel.org/pub/scm/linux/kernel/git/mripard/linux:
  clk: sunxi-ng: Fix wrong reset register offsets
  clk: sunxi-ng: nk: Make ccu_nk_find_best static
  clk: sunxi-ng: Fix inverted test condition in ccu_helper_wait_for_lock
  clk: sunxi: Fix return value check in sun8i_a23_mbus_setup()
  clk: sunxi: pll2: Fix return value check in sun4i_pll2_setup()
condition.
 -----BEGIN PGP SIGNATURE-----
 Version: GnuPG v2

 iQEcBAABCAAGBQJX0WAXAAoJEEp/3jgCEfOL8bEIAIeVmaU+M/1HuPucc+xiUooy
 IP+LNjhSc52neqDsN/eYjTn4zipu0ZAojPW9geGkPHOnKTKdRqkNLpyWaQcSv0AG
 yOUiJxnfwZ2LuOD2L/EIzqSKWo1lrdhIP/tSyRk0cOhlXn8urKatEOQi1+8H3Jlr
 gzD2PZzXL1jnpCiGPnuYLlh6wmk9Su+7+GCkNOwi1z+j+sM5AupZESPsh6Ze+bYk
 xgii4e21cBQv4NXojLECnfNez3HjYJCqYAUZ55lzSneUkbTRdBoY+pye/FeFKIBe
 9Wb5IRYzvih9Bcdpx+o5RZtCoKhq1XRngjjvv7cHYELQ0JVM4kFwEKrUHMoHhWU=
 =VDDm
 -----END PGP SIGNATURE-----

Merge tag 'ceph-for-4.8-rc6' of git://github.com/ceph/ceph-client

Pull ceph fix from Ilya Dryomov:
 "A fix for a 4.7 performance regression, caused by a typo in an if
  condition"

* tag 'ceph-for-4.8-rc6' of git://github.com/ceph/ceph-client:
  ceph: do not modify fi->frag in need_reset_readdir()
Pull dmi fix from Jean Delvare.

* 'dmi-for-linus' of git://git.kernel.org/pub/scm/linux/kernel/git/jdelvare/staging:
  dmi-id: don't free dev structure after calling device_register
This is a slightly larger batch of fixes that we've been sitting on a few
 -rcs. Most of them are simple oneliners, but there are two sets that are
 slightly larger and worth pointing out:

  - A set of patches to OMAP to deal with hwmod for RTC on am33xx (beaglebone
    SoC, among others). It's the only clock that ever has a valid offset of 0,
    so a new flag needed introduction once this problem was discovered.

  - A collection of CCI fixes for performance counters discovered once people
    started using it on X-Gene CPUs.
 -----BEGIN PGP SIGNATURE-----
 Version: GnuPG v1

 iQIcBAABAgAGBQJX0OnNAAoJEIwa5zzehBx3C80P/3Adca+87uQPI57AWJL7TIU3
 i9YAf1povBg/u5PHn2XiNj2gBeYtDL6vKTbca9zDX/ezSPaGFAp1nPsUG3m4yKLG
 0FjkNRan+FvFoi195TxANrBeYE39/ZNWJCsPn01+2Q2EsYnlCn9wsFglxTQGObsN
 MI2rgYVxabdJC8TO5WuGUdJEa9TynU65fdqdD+KR+DfA8yOyu9wZEmE1JuHprUCQ
 H2MYYHHFZD5Y41/Y/SvdDVprCOd8lq8Syt7Vk1O6pQKQSGgojgGn36YJeBIapnOy
 4y1/FFqoRe5FwSbt934q/4P/QpHwnGvIFi0edS+Reb6/3gUWRchQ8Dt1I1C/2QoJ
 J+7KQKR4SBSiu6LnsP8gNOAqulpyGzwE2aHBVD1mpbPIynA7G5MfI1pEJw4nVvFQ
 rAlBmuVzjaysuhKAdM32fd34dVwQljDiqh4qWtk0hbgjyPpdxT7QjIwSCR6vfbzo
 toOKQ2eiIqF+syOAnXbpPSmtaURavxvBim4DEXQfVHUbFHVErZ5zHmwGWjDc5vLT
 WixQ62hilHc08pcalY31RF3k21GwBXBVDf6clQ/9TDCErlCAlpjyN0/4ZrRpcYwz
 NHpFdbBNLzW0VJ0gHtwb+Xz4qgcUneTxXDUTaU46MYRquML/uqXMFrkJUQEOq1h5
 nPGe55ItupK8REaMCJv/
 =8pPd
 -----END PGP SIGNATURE-----

Merge tag 'armsoc-fixes' of git://git.kernel.org/pub/scm/linux/kernel/git/arm/arm-soc

Pull ARM SoC fixes from Olof Johansson:
 "This is a slightly larger batch of fixes that we've been sitting on a
  few -rcs.  Most of them are simple oneliners, but there are two sets
  that are slightly larger and worth pointing out:

   - A set of patches to OMAP to deal with hwmod for RTC on am33xx
     (beaglebone SoC, among others).  It's the only clock that ever has
     a valid offset of 0, so a new flag needed introduction once this
     problem was discovered.

   - A collection of CCI fixes for performance counters discovered once
     people started using it on X-Gene CPUs"

* tag 'armsoc-fixes' of git://git.kernel.org/pub/scm/linux/kernel/git/arm/arm-soc: (37 commits)
  arm-cci: pmu: Fix typo in event name
  Revert "ARM: tegra: fix erroneous address in dts"
  ARM: dts: imx6qdl: Fix SPDIF regression
  ARM: imx6: add missing BM_CLPCR_BYPASS_PMIC_READY setting for imx6sx
  ARM: dts: imx7d-sdb: fix ti,x-plate-ohms property name
  ARM: dts: kirkwood: Fix PCIe label on OpenRD
  ARM: kirkwood: ib62x0: fix size of u-boot environment partition
  bus: arm-ccn: make event groups reliable
  bus: arm-ccn: fix hrtimer registration
  bus: arm-ccn: fix PMU interrupt flags
  ARM: tegra: Correct polarity for Tegra114 PMIC interrupt
  MAINTAINERS: add tree entry for ARM/UniPhier architecture
  ARM: sun5i: Fix typo in trip point temperature
  MAINTAINERS: Switch to kernel.org account for Krzysztof Kozlowski
  ARM: imx6ul: populates platform device at .init_machine
  bus: arm-ccn: Add missing event attribute exclusions for host/guest
  bus: arm-ccn: Correct required arguments for XP PMU events
  bus: arm-ccn: Fix XP watchpoint settings bitmask
  bus: arm-ccn: Do not attempt to configure XPs for cycle counter
  bus: arm-ccn: Fix PMU handling of MN
  ...
The md-cluster is compiled as module by default,
if it is compiled by built-in way, then we can't
make md-cluster works.

[64782.630008] md/raid1:md127: active with 2 out of 2 mirrors
[64782.630528] md-cluster module not found.
[64782.630530] md127: Could not setup cluster service (-2)

Fixes: edb39c9 ("Introduce md_cluster_operations to handle cluster functions")
Cc: stable@vger.kernel.org (v4.1+)
Reported-by: Marc Smith <marc.smith@mcc.edu>
Reviewed-by: NeilBrown <neilb@suse.com>
Signed-off-by: Guoqing Jiang <gqjiang@suse.com>
Signed-off-by: Shaohua Li <shli@fb.com>
gb_phy runtime functions use struct gbphy_device *gbphy_dev,
and not struct device. When CONFIG_PM_RUNTIME is not enabled
a compile error will show.

Fix this by passing struct gbphy_device * as parameter

Testing Done: compile with CONFIG_PM_RUNTIME disabled

Signed-off-by: Axel Haslam <ahaslam@baylibre.com>
Reviewed-by: Alex Elder <elder@linaro.org>
Signed-off-by: Greg Kroah-Hartman <gregkh@google.com>
MIPS Enhanced Virtual Addressing (EVA) allows the virtual memory
segments to be rearranged such that the KSeg0/KSeg1 segments are
accessible TLB mapped to user mode, which would trigger a TLB Miss
exception (due to lack of TLB mappings) instead of an Address Error
exception.

Update the TLB Miss handling similar to Address Error handling for guest
MMIO emulation.

Signed-off-by: James Hogan <james.hogan@imgtec.com>
Cc: Paolo Bonzini <pbonzini@redhat.com>
Cc: "Radim Krčmář" <rkrcmar@redhat.com>
Cc: Ralf Baechle <ralf@linux-mips.org>
Cc: linux-mips@linux-mips.org
Cc: kvm@vger.kernel.org
MIPS Enhanced Virtual Addressing (EVA) allows the user mode and kernel
mode address spaces to overlap, breaking the assumption that PAGE_OFFSET
is an appropriate KVM HVA error value, since PAGE_OFFSET may be as low
as zero.

Fix this in the same way that s390 does in commit bf640876e2 ("KVM:
s390: Make KVM_HVA_ERR_BAD usable on s390"), by overriding
KVM_HVA_ERR_[RO_]BAD and kvm_is_error_hva() in asm/kvm_host.h.

Signed-off-by: James Hogan <james.hogan@imgtec.com>
Cc: Paolo Bonzini <pbonzini@redhat.com>
Cc: "Radim Krčmář" <rkrcmar@redhat.com>
Cc: Ralf Baechle <ralf@linux-mips.org>
Cc: linux-mips@linux-mips.org
Cc: kvm@vger.kernel.org
'make -C tools/perf build-test' is failing with below log for poewrpc.

  In file included from /tmp/tmp.3eEwmGlYaF/perf-4.8.0-rc4/tools/perf/perf.h:15:0,
                   from util/cpumap.h:8,
                   from util/env.c:1:
  /tmp/tmp.3eEwmGlYaF/perf-4.8.0-rc4/tools/perf/perf-sys.h:23:56:
  fatal error: ../../arch/powerpc/include/uapi/asm/unistd.h: No such file or directory
  compilation terminated.

I bisected it and found it's failing from commit ad430729ae ("Remove:
kernel unistd*h files from perf's MANIFEST, not used").

Header file '../../arch/powerpc/include/uapi/asm/unistd.h' is included
only for powerpc in tools/perf/perf-sys.h.

By looking closly at commit history, I found little weird thing:

Commit f2d9cae9ea ("perf powerpc: Use uapi/unistd.h to fix build
error") replaced 'asm/unistd.h' with 'uapi/asm/unistd.h'

Commit d2709c7ce4 ("perf: Make perf build for x86 with UAPI
disintegration applied") removes all arch specific 'uapi/asm/unistd.h'
for all archs and adds generic <asm/unistd.h>.

Commit f0b9abfb04 ("Merge branch 'linus' into perf/core") again
includes 'uapi/asm/unistd.h' for powerpc. Don't know how exactly this
happened as this change is not part of commit also.

Signed-off-by: Ravi Bangoria <ravi.bangoria@linux.vnet.ibm.com>
Cc: Alexander Shishkin <alexander.shishkin@linux.intel.com>
Cc: Peter Zijlstra <peterz@infradead.org>
Link: http://lkml.kernel.org/r/1472630591-5089-1-git-send-email-ravi.bangoria@linux.vnet.ibm.com
Fixes: ad430729ae ("Remove: kernel unistd*h files from perf's MANIFEST, not used")
Signed-off-by: Arnaldo Carvalho de Melo <acme@redhat.com>
The perf tools can read a cpumask file for a PMU, describing a subset of
CPUs which that PMU covers. So far this has only been used to cater for
uncore PMUs, which in practice happen to only have a single CPU
described in the mask.

Until recently, the perf tools only correctly handled cpumask containing
a single CPU, and only when monitoring in system-wide mode. For example,
prior to commit 00e727bb38 ("perf stat: Balance opening and
reading events"), a mask with more than a single CPU could cause perf
stat to hang. When a CPU PMU covers a subset of CPUs, but lacks a
cpumask, perf record will fail to open events (on the cores the PMU does
not support), and gives up.

For systems with heterogeneous CPUs such as ARM big.LITTLE systems, this
presents a problem. We have a PMU for each microarchitecture (e.g. a big
PMU and a little PMU), and would like to expose a cpumask for each (so
as to allow perf record and other tools to do the right thing). However,
doing so kernel-side will cause old perf binaries to not function (e.g.
hitting the issue solved by 00e727bb38), and thus commits the
cardinal sin of breaking (existing) userspace.

To address this chicken-and-egg problem, this patch adds support got a
new file, cpus, which is largely identical to the existing cpumask file.
A kernel can expose this file, knowing that new perf binaries will
correctly support it, while old perf binaries will not look for it (and
thus will not be broken).

Signed-off-by: Mark Rutland <mark.rutland@arm.com>
Cc: Alexander Shishkin <alexander.shishkin@linux.intel.com>
Cc: Jiri Olsa <jolsa@kernel.org>
Cc: Mark Rutland <mark.rutland@arm.com>
Cc: Peter Zijlstra <peterz@infradead.org>
Cc: Will Deacon <will.deacon@arm.com>
Link: http://lkml.kernel.org/r/1473330112-28528-8-git-send-email-mark.rutland@arm.com
Signed-off-by: Arnaldo Carvalho de Melo <acme@redhat.com>
In systems with heterogeneous CPU PMUs, it's possible for each evsel to
cover a distinct set of CPUs, and hence the cpu_map associated with each
evsel may have a distinct idx<->id mapping. Any of these may be distinct
from the evlist's cpu map.

Events can be tied to the same fd so long as they use the same per-cpu
ringbuffer (i.e. so long as they are on the same CPU). To acquire the
correct FDs, we must compare the Linux logical IDs rather than the evsel
or evlist indices.

This path adds logic to perf_evlist__mmap_per_evsel to handle this,
translating IDs as required. As PMUs may cover a subset of CPUs from the
evlist, we skip the CPUs a PMU cannot handle.

Without this patch, perf record may try to mmap erroneous FDs on
heterogeneous systems, and will bail out early rather than running the
workload.

Signed-off-by: Mark Rutland <mark.rutland@arm.com>
Acked-by: Jiri Olsa <jolsa@kernel.org>
Cc: Alexander Shishkin <alexander.shishkin@linux.intel.com>
Cc: Mark Rutland <mark.rutland@arm.com>
Cc: Peter Zijlstra <peterz@infradead.org>
Cc: Will Deacon <will.deacon@arm.com>
Link: http://lkml.kernel.org/r/1473330112-28528-7-git-send-email-mark.rutland@arm.com
Signed-off-by: Arnaldo Carvalho de Melo <acme@redhat.com>
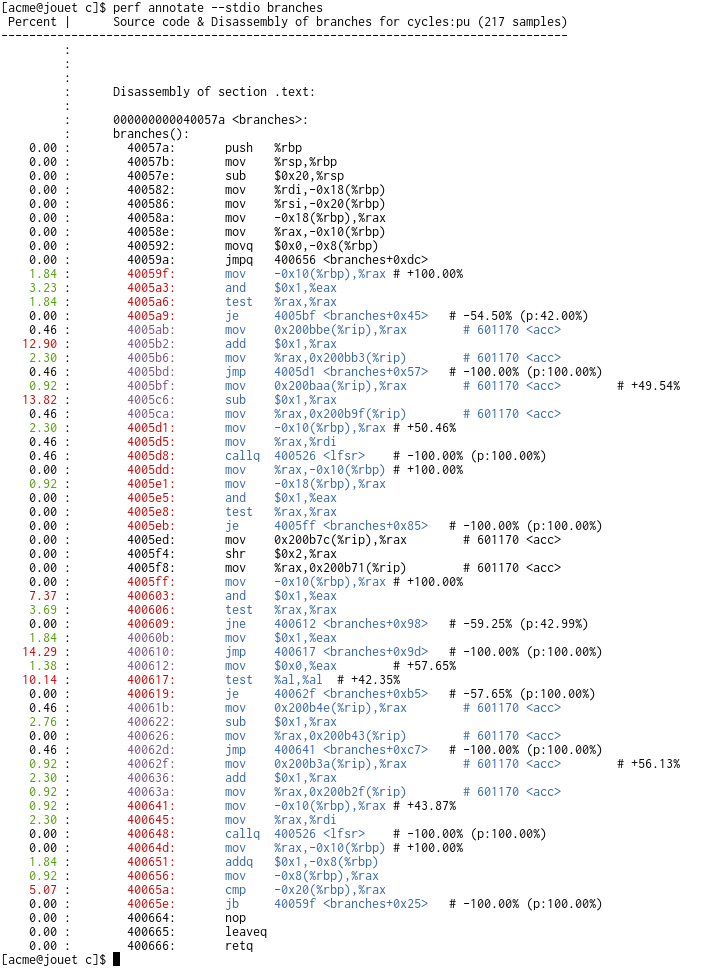
I wanted to know the hottest path through a function and figured the
branch-stack (LBR) information should be able to help out with that.

The below uses the branch-stack to create basic blocks and generate
statistics from them.

        from    to              branch_i
        * ----> *
                |
                | block
                v
                * ----> *
                from    to      branch_i+1

The blocks are broken down into non-overlapping ranges, while tracking
if the start of each range is an entry point and/or the end of a range
is a branch.

Each block iterates all ranges it covers (while splitting where required
to exactly match the block) and increments the 'coverage' count.

For the range including the branch we increment the taken counter, as
well as the pred counter if flags.predicted.

Using these number we can find if an instruction:

 - had coverage; given by:

        br->coverage / br->sym->max_coverage

   This metric ensures each symbol has a 100% spot, which reflects the
   observation that each symbol must have a most covered/hottest
   block.

 - is a branch target: br->is_target && br->start == add

 - for targets, how much of a branch's coverages comes from it:

	target->entry / branch->coverage

 - is a branch: br->is_branch && br->end == addr

 - for branches, how often it was taken:

        br->taken / br->coverage

   after all, all execution that didn't take the branch would have
   incremented the coverage and continued onward to a later branch.

 - for branches, how often it was predicted:

        br->pred / br->taken

The coverage percentage is used to color the address and asm sections;
for low (<1%) coverage we use NORMAL (uncolored), indicating that these
instructions are not 'important'. For high coverage (>75%) we color the
address RED.

For each branch, we add an asm comment after the instruction with
information on how often it was taken and predicted.

Output looks like (sans color, which does loose a lot of the
information :/)

$ perf record --branch-filter u,any -e cycles:p ./branches 27
$ perf annotate branches

 Percent |	Source code & Disassembly of branches for cycles:pu (217 samples)
---------------------------------------------------------------------------------
         :	branches():
    0.00 :	  40057a:       push   %rbp
    0.00 :	  40057b:       mov    %rsp,%rbp
    0.00 :	  40057e:       sub    $0x20,%rsp
    0.00 :	  400582:       mov    %rdi,-0x18(%rbp)
    0.00 :	  400586:       mov    %rsi,-0x20(%rbp)
    0.00 :	  40058a:       mov    -0x18(%rbp),%rax
    0.00 :	  40058e:       mov    %rax,-0x10(%rbp)
    0.00 :	  400592:       movq   $0x0,-0x8(%rbp)
    0.00 :	  40059a:       jmpq   400656 <branches+0xdc>
    1.84 :	  40059f:       mov    -0x10(%rbp),%rax	# +100.00%
    3.23 :	  4005a3:       and    $0x1,%eax
    1.84 :	  4005a6:       test   %rax,%rax
    0.00 :	  4005a9:       je     4005bf <branches+0x45>	# -54.50% (p:42.00%)
    0.46 :	  4005ab:       mov    0x200bbe(%rip),%rax        # 601170 <acc>
   12.90 :	  4005b2:       add    $0x1,%rax
    2.30 :	  4005b6:       mov    %rax,0x200bb3(%rip)        # 601170 <acc>
    0.46 :	  4005bd:       jmp    4005d1 <branches+0x57>	# -100.00% (p:100.00%)
    0.92 :	  4005bf:       mov    0x200baa(%rip),%rax        # 601170 <acc>	# +49.54%
   13.82 :	  4005c6:       sub    $0x1,%rax
    0.46 :	  4005ca:       mov    %rax,0x200b9f(%rip)        # 601170 <acc>
    2.30 :	  4005d1:       mov    -0x10(%rbp),%rax	# +50.46%
    0.46 :	  4005d5:       mov    %rax,%rdi
    0.46 :	  4005d8:       callq  400526 <lfsr>	# -100.00% (p:100.00%)
    0.00 :	  4005dd:       mov    %rax,-0x10(%rbp)	# +100.00%
    0.92 :	  4005e1:       mov    -0x18(%rbp),%rax
    0.00 :	  4005e5:       and    $0x1,%eax
    0.00 :	  4005e8:       test   %rax,%rax
    0.00 :	  4005eb:       je     4005ff <branches+0x85>	# -100.00% (p:100.00%)
    0.00 :	  4005ed:       mov    0x200b7c(%rip),%rax        # 601170 <acc>
    0.00 :	  4005f4:       shr    $0x2,%rax
    0.00 :	  4005f8:       mov    %rax,0x200b71(%rip)        # 601170 <acc>
    0.00 :	  4005ff:       mov    -0x10(%rbp),%rax	# +100.00%
    7.37 :	  400603:       and    $0x1,%eax
    3.69 :	  400606:       test   %rax,%rax
    0.00 :	  400609:       jne    400612 <branches+0x98>	# -59.25% (p:42.99%)
    1.84 :	  40060b:       mov    $0x1,%eax
   14.29 :	  400610:       jmp    400617 <branches+0x9d>	# -100.00% (p:100.00%)
    1.38 :	  400612:       mov    $0x0,%eax	# +57.65%
   10.14 :	  400617:       test   %al,%al	# +42.35%
    0.00 :	  400619:       je     40062f <branches+0xb5>	# -57.65% (p:100.00%)
    0.46 :	  40061b:       mov    0x200b4e(%rip),%rax        # 601170 <acc>
    2.76 :	  400622:       sub    $0x1,%rax
    0.00 :	  400626:       mov    %rax,0x200b43(%rip)        # 601170 <acc>
    0.46 :	  40062d:       jmp    400641 <branches+0xc7>	# -100.00% (p:100.00%)
    0.92 :	  40062f:       mov    0x200b3a(%rip),%rax        # 601170 <acc>	# +56.13%
    2.30 :	  400636:       add    $0x1,%rax
    0.92 :	  40063a:       mov    %rax,0x200b2f(%rip)        # 601170 <acc>
    0.92 :	  400641:       mov    -0x10(%rbp),%rax	# +43.87%
    2.30 :	  400645:       mov    %rax,%rdi
    0.00 :	  400648:       callq  400526 <lfsr>	# -100.00% (p:100.00%)
    0.00 :	  40064d:       mov    %rax,-0x10(%rbp)	# +100.00%
    1.84 :	  400651:       addq   $0x1,-0x8(%rbp)
    0.92 :	  400656:       mov    -0x8(%rbp),%rax
    5.07 :	  40065a:       cmp    -0x20(%rbp),%rax
    0.00 :	  40065e:       jb     40059f <branches+0x25>	# -100.00% (p:100.00%)
    0.00 :	  400664:       nop
    0.00 :	  400665:       leaveq
    0.00 :	  400666:       retq

(Note: the --branch-filter u,any was used to avoid spurious target and
branch points due to interrupts/faults, they show up as very small -/+
annotations on 'weird' locations)

Committer note:

Please take a look at:

  http://vger.kernel.org/~acme/perf/annotate_basic_blocks.png

To see the colors.

Signed-off-by: Peter Zijlstra (Intel) <peterz@infradead.org>
Tested-by: Arnaldo Carvalho de Melo <acme@redhat.com>
Cc: Alexander Shishkin <alexander.shishkin@linux.intel.com>
Cc: Andi Kleen <andi@firstfloor.org>
Cc: Anshuman Khandual <khandual@linux.vnet.ibm.com>
Cc: David Carrillo-Cisneros <davidcc@google.com>
Cc: Jiri Olsa <jolsa@kernel.org>
Cc: Kan Liang <kan.liang@intel.com>
Cc: Linus Torvalds <torvalds@linux-foundation.org>
Cc: Namhyung Kim <namhyung@kernel.org>
Cc: Stephane Eranian <eranian@google.com>
[ Moved sym->max_coverage to 'struct annotate', aka symbol__annotate(sym) ]
Signed-off-by: Arnaldo Carvalho de Melo <acme@redhat.com>
The number of Ion ioctls may continue to grow along with necessary
validation. Pull it out into a separate file for easier management
and review.

Signed-off-by: Laura Abbott <labbott@redhat.com>
Acked-by: Arnd Bergmann <arnd@arndb.de>
Signed-off-by: Greg Kroah-Hartman <gregkh@linuxfoundation.org>
When synthesizing mmap events, add MAP_HUGETLB map flag if the source of
mapping is file in hugetlbfs.

After this patch, perf can identify hugetlb mapping even if perf is
started after the mapping of huge pages (like with 'perf top').

Signed-off-by: Wang Nan <wangnan0@huawei.com>
Reviewed-by: Nilay Vaish <nilayvaish@gmail.com>
Cc: He Kuang <hekuang@huawei.com>
Cc: Hou Pengyang <houpengyang@huawei.com>
Cc: Zefan Li <lizefan@huawei.com>
Link: http://lkml.kernel.org/r/1473137909-142064-4-git-send-email-wangnan0@huawei.com
Signed-off-by: Arnaldo Carvalho de Melo <acme@redhat.com>
Detect hugetlbfs. hugetlbfs__mountpoint() will be used during recording
to help identifying hugetlb mmaps: which should be recognized as anon
mapping.

Signed-off-by: Wang Nan <wangnan0@huawei.com>
Reviewed-by: Nilay Vaish <nilayvaish@gmail.com>
Cc: He Kuang <hekuang@huawei.com>
Cc: Hou Pengyang <houpengyang@huawei.com>
Cc: Zefan Li <lizefan@huawei.com>
Link: http://lkml.kernel.org/r/1473137909-142064-3-git-send-email-wangnan0@huawei.com
Signed-off-by: Arnaldo Carvalho de Melo <acme@redhat.com>
The Zynq FPGA manager driver serves no purpose on other architectures
so hide it unless build-testing.

Signed-off-by: Jean Delvare <jdelvare@suse.de>
Acked-by: Moritz Fischer <moritz.fischer@ettus.com>
Acked-by: Alan Tull <atull@opensource.altera.com>
Acked-by: Michal Simek <michal.simek@xilinx.com>
Cc: "Sören Brinkmann" <soren.brinkmann@xilinx.com>
Signed-off-by: Greg Kroah-Hartman <gregkh@linuxfoundation.org>
Hugetlbfs mapping should be recognized as anon mapping so user has a
chance to create /tmp/perf-<pid>.map file for symbol resolving. This
patch utilizes MAP_HUGETLB to identify hugetlb mapping.

After this patch, if perf is started before a program starts using huge
pages (so perf gets MMAP2 events from kernel), perf is able to recognize
hugetlb mapping as anon mapping.

Signed-off-by: Wang Nan <wangnan0@huawei.com>
Cc: He Kuang <hekuang@huawei.com>
Cc: Nilay Vaish <nilayvaish@gmail.com>
Cc: Zefan Li <lizefan@huawei.com>
Link: http://lkml.kernel.org/r/1473137909-142064-2-git-send-email-wangnan0@huawei.com
Signed-off-by: Hou Pengyang <houpengyang@huawei.com>
Signed-off-by: Arnaldo Carvalho de Melo <acme@redhat.com>
Make it clear that adding slave support shall not disable master
functionality. We can have both, so we should.

Signed-off-by: Wolfram Sang <wsa@the-dreams.de>
We can't use a static property for all the changesets, so we now create
dynamic ones for each changeset.

Signed-off-by: Wolfram Sang <wsa+renesas@sang-engineering.com>
Fixes: 50a5ba8769 ("i2c: mux: demux-pinctrl: add driver")
Signed-off-by: Wolfram Sang <wsa@the-dreams.de>
When booting a kvm guest on AMD with the latest kernel the following
messages are displayed in the boot log:

 tsc: Unable to calibrate against PIT
 tsc: HPET/PMTIMER calibration failed

aa297292d7 ("x86/tsc: Enumerate SKL cpu_khz and tsc_khz via CPUID")
introduced a change to account for a difference in cpu and tsc frequencies for
Intel SKL processors. Before this change the native tsc set
x86_platform.calibrate_tsc to native_calibrate_tsc() which is a hardware
calibration of the tsc, and in tsc_init() executed

	tsc_khz = x86_platform.calibrate_tsc();
	cpu_khz = tsc_khz;

The kvm code changed x86_platform.calibrate_tsc to kvm_get_tsc_khz() and
executed the same tsc_init() function.  This meant that KVM guests did not
execute the native hardware calibration function.

After aa297292d7, there are separate native calibrations for cpu_khz and
tsc_khz.  The code sets x86_platform.calibrate_tsc to native_calibrate_tsc()
which is now an Intel specific calibration function, and
x86_platform.calibrate_cpu to native_calibrate_cpu() which is the "old"
native_calibrate_tsc() function (ie, the native hardware calibration
function).

tsc_init() now does

	cpu_khz = x86_platform.calibrate_cpu();
	tsc_khz = x86_platform.calibrate_tsc();
	if (tsc_khz == 0)
		tsc_khz = cpu_khz;
	else if (abs(cpu_khz - tsc_khz) * 10 > tsc_khz)
		cpu_khz = tsc_khz;

The kvm code should not call the hardware initialization in
native_calibrate_cpu(), as it isn't applicable for kvm and it didn't do that
prior to aa297292d7.

This patch resolves this issue by setting x86_platform.calibrate_cpu to
kvm_get_tsc_khz().

v2: I had originally set x86_platform.calibrate_cpu to
cpu_khz_from_cpuid(), however, pbonzini pointed out that the CPUID leaf
in that function is not available in KVM.  I have changed the function
pointer to kvm_get_tsc_khz().

Fixes: aa297292d7 ("x86/tsc: Enumerate SKL cpu_khz and tsc_khz via CPUID")
Signed-off-by: Prarit Bhargava <prarit@redhat.com>
Cc: Paolo Bonzini <pbonzini@redhat.com>
Cc: Radim Krčmář <rkrcmar@redhat.com>
Cc: Thomas Gleixner <tglx@linutronix.de>
Cc: Ingo Molnar <mingo@redhat.com>
Cc: "H. Peter Anvin" <hpa@zytor.com>
Cc: x86@kernel.org
Cc: Len Brown <len.brown@intel.com>
Cc: "Peter Zijlstra (Intel)" <peterz@infradead.org>
Cc: Borislav Petkov <bp@suse.de>
Cc: Adrian Hunter <adrian.hunter@intel.com>
Cc: "Christopher S. Hall" <christopher.s.hall@intel.com>
Cc: David Woodhouse <dwmw2@infradead.org>
Cc: kvm@vger.kernel.org
Signed-off-by: Paolo Bonzini <pbonzini@redhat.com>
The fsl,panel property is deprecated and we should use the new
of_graph dt bindings to describe the relationship between the DCU
controller and the panel.

Signed-off-by: Stefan Agner <stefan@agner.ch>
Signed-off-by: Shawn Guo <shawnguo@kernel.org>
The imx6ul soc code gained support for cpuidle, but that causes
a link failure if CONFIG_SOC_IMX6SX is disabled:

arch/arm/mach-imx/mach-imx6ul.o: In function `imx6ul_init_late':
mach-imx6ul.c:(.init.text+0xc): undefined reference to `imx6sx_cpuidle_init'

This adds the file containing the imx6sx_cpuidle_init function
to the kernel for 6ul-only configurations.

Signed-off-by: Arnd Bergmann <arnd@arndb.de>
Fixes: 547e8f5269 ("ARM: imx: add cpuidle support for i.mx6ul")
Signed-off-by: Shawn Guo <shawnguo@kernel.org>
add of_graph dt nodes to describe the panel, and removed
"fsl,panel" property

Signed-off-by: Meng Yi <meng.yi@nxp.com>
Acked-by: Stefan Agner <stefan@agner.ch>
Signed-off-by: Shawn Guo <shawnguo@kernel.org>